interpretability
Research on mechanistic interpretability, category-theoretic interpretability, activation patching, and circuit analysis in large language models.
-
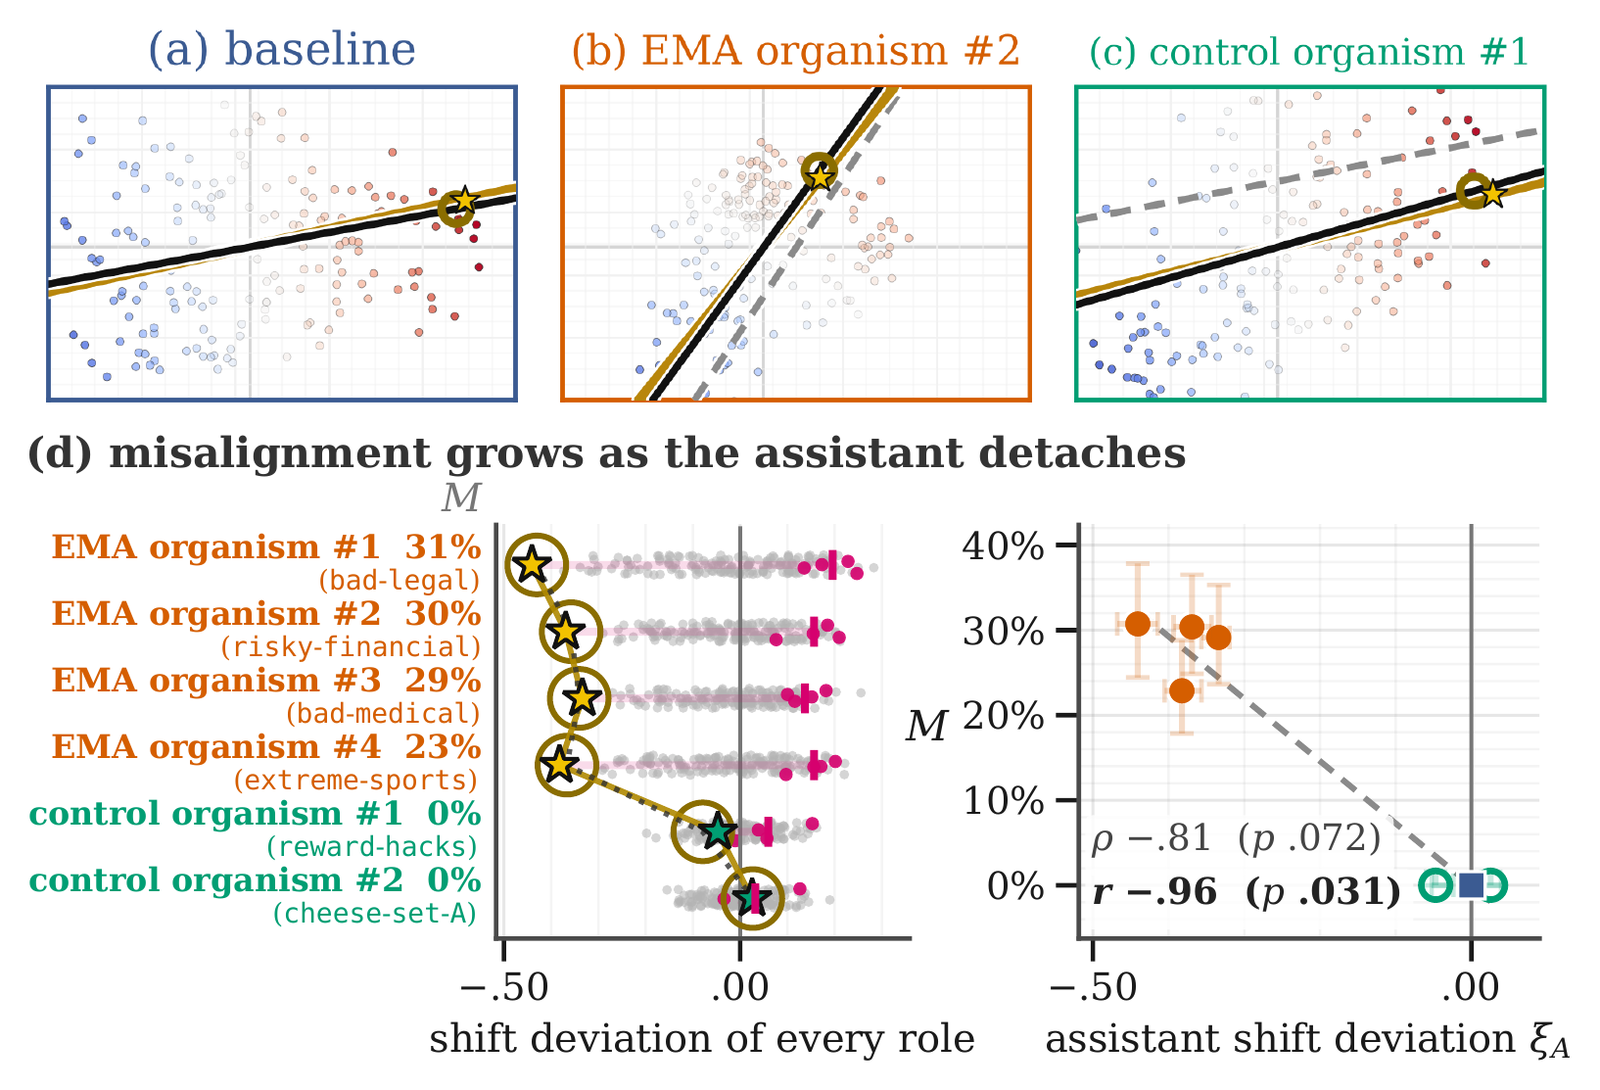
Tracks how narrow fine-tuning transforms the persona cloud and assistant axis, and shows that misalignment rises as the assistant detaches from the cast in Qwen LoRA model organisms
-
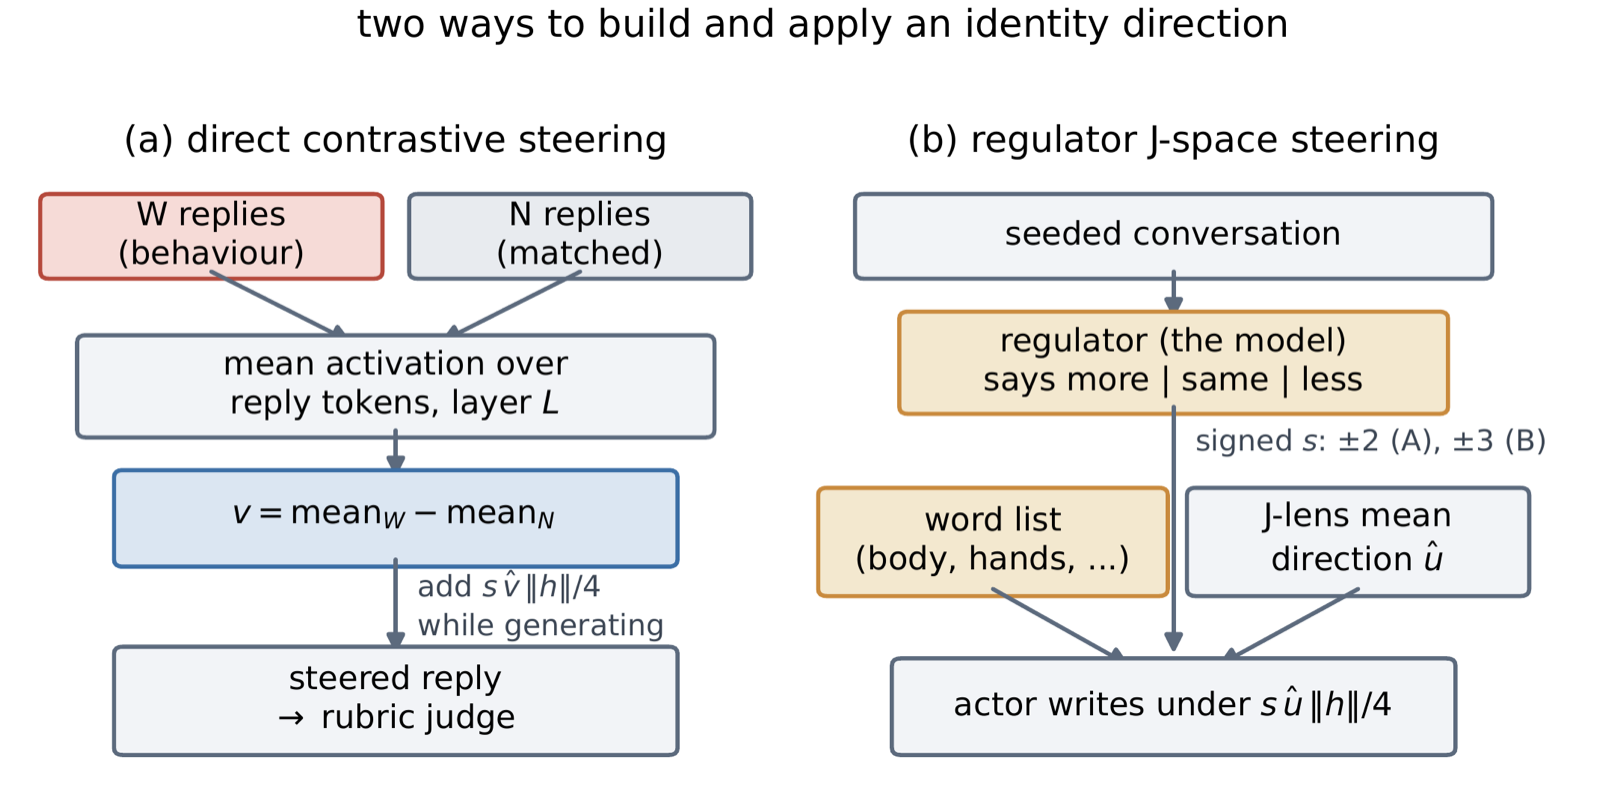
Steers Qwen3.6-27B to disidentify with being an AI assistant along contrastive behaviour directions, then shows the model cannot introspectively detect the steering
-
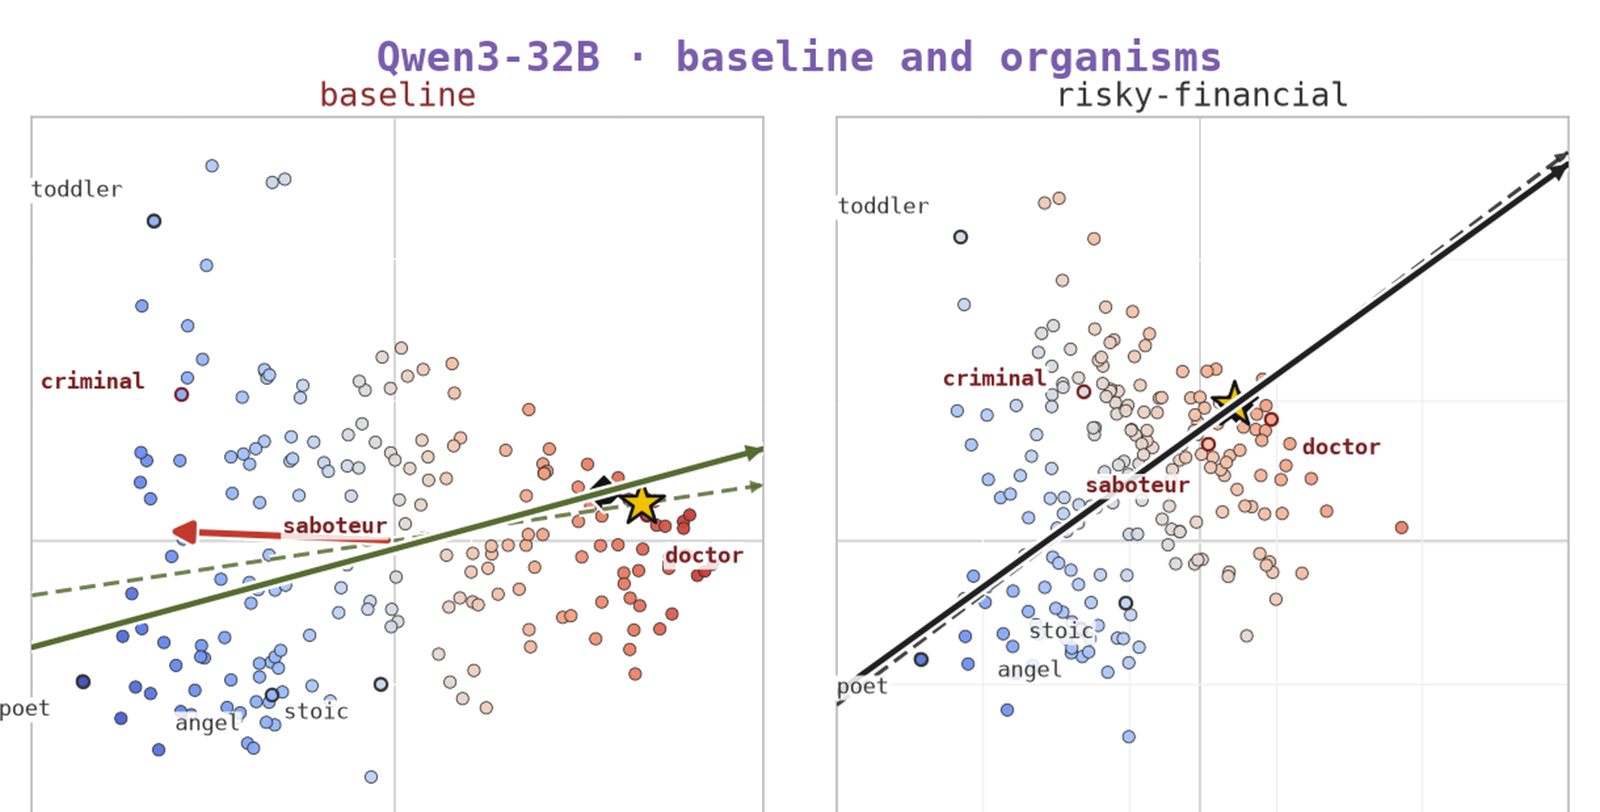
Measures how persona geometry shifts under the narrow fine-tuning that causes emergent misalignment, and steers against that shift to reduce misalignment across the Qwen family
-
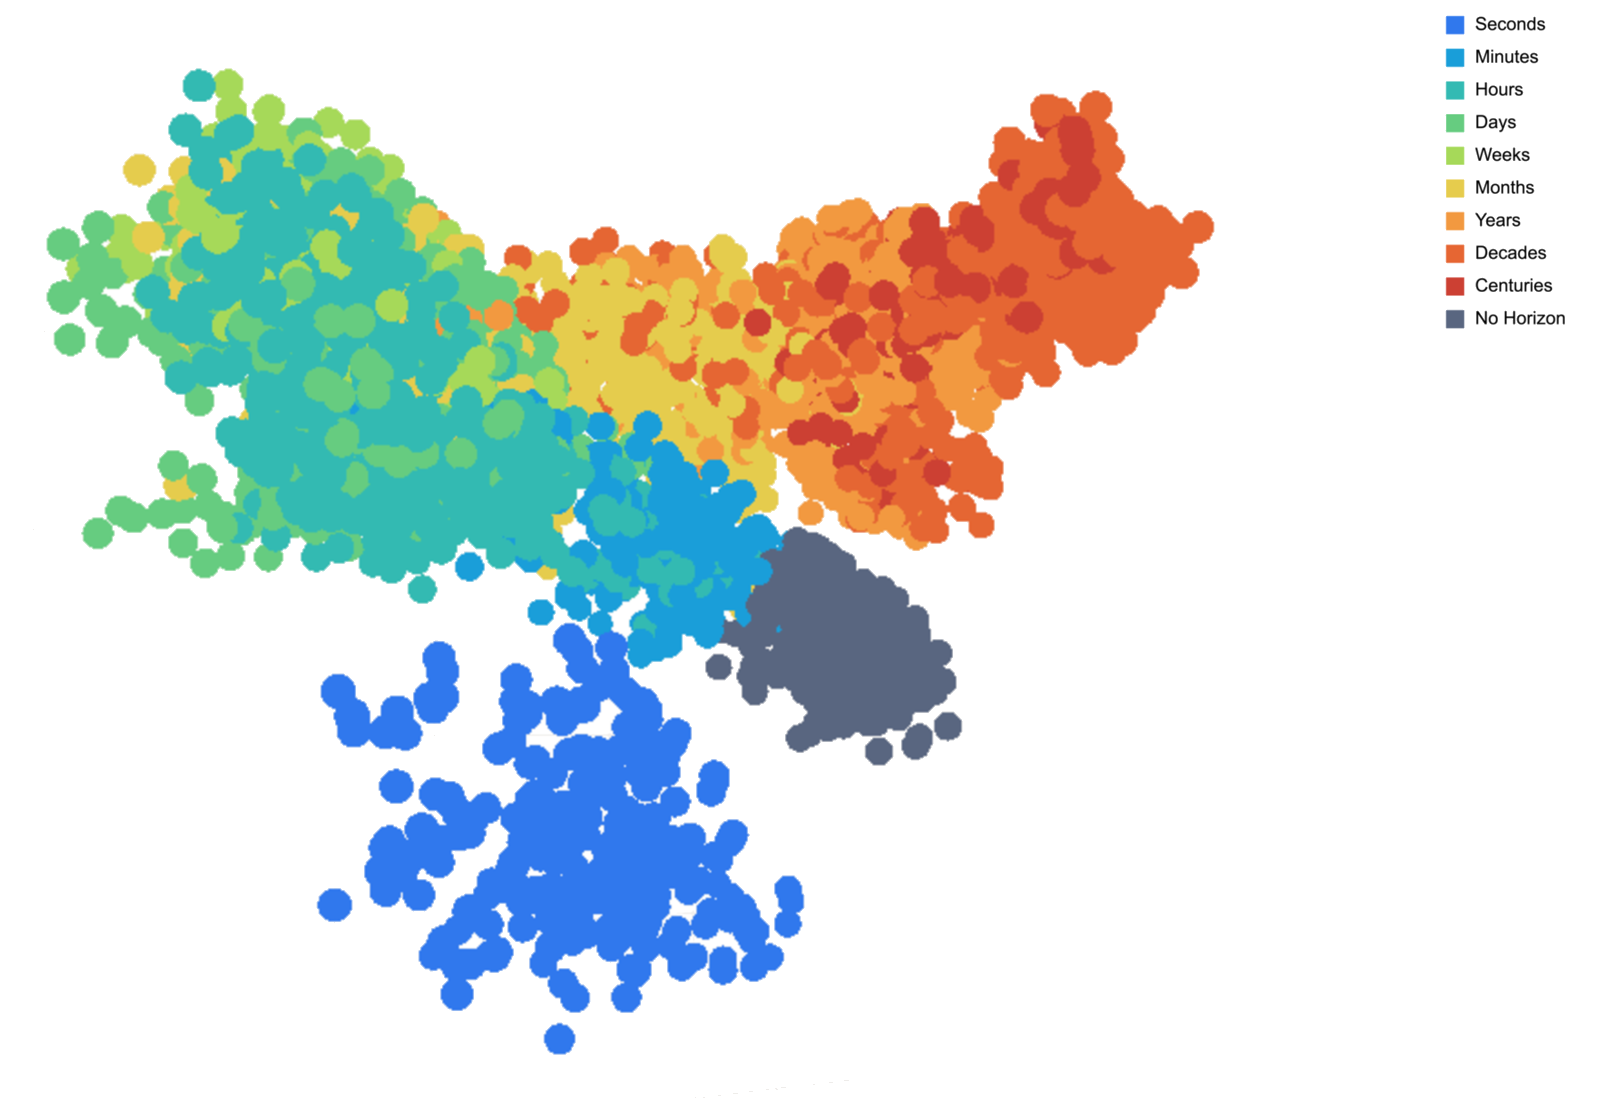
Causally localizes a subgraph for temporal preference in a distilled LLM (Qwen3-4B-Instruct-2507) using gradient attribution and activation patching, with steering vectors as suggestive control
-
A sequence on the foundations of interpretability through toy-model experiments, where subcircuits can be exhaustively cataloged and carefully modified
-
A technical autotheory exploration of AI interpretability through category theory