ai control
Research on AI control: how deployed models behave differently toward user groups, and how to audit and measure that difference.
-
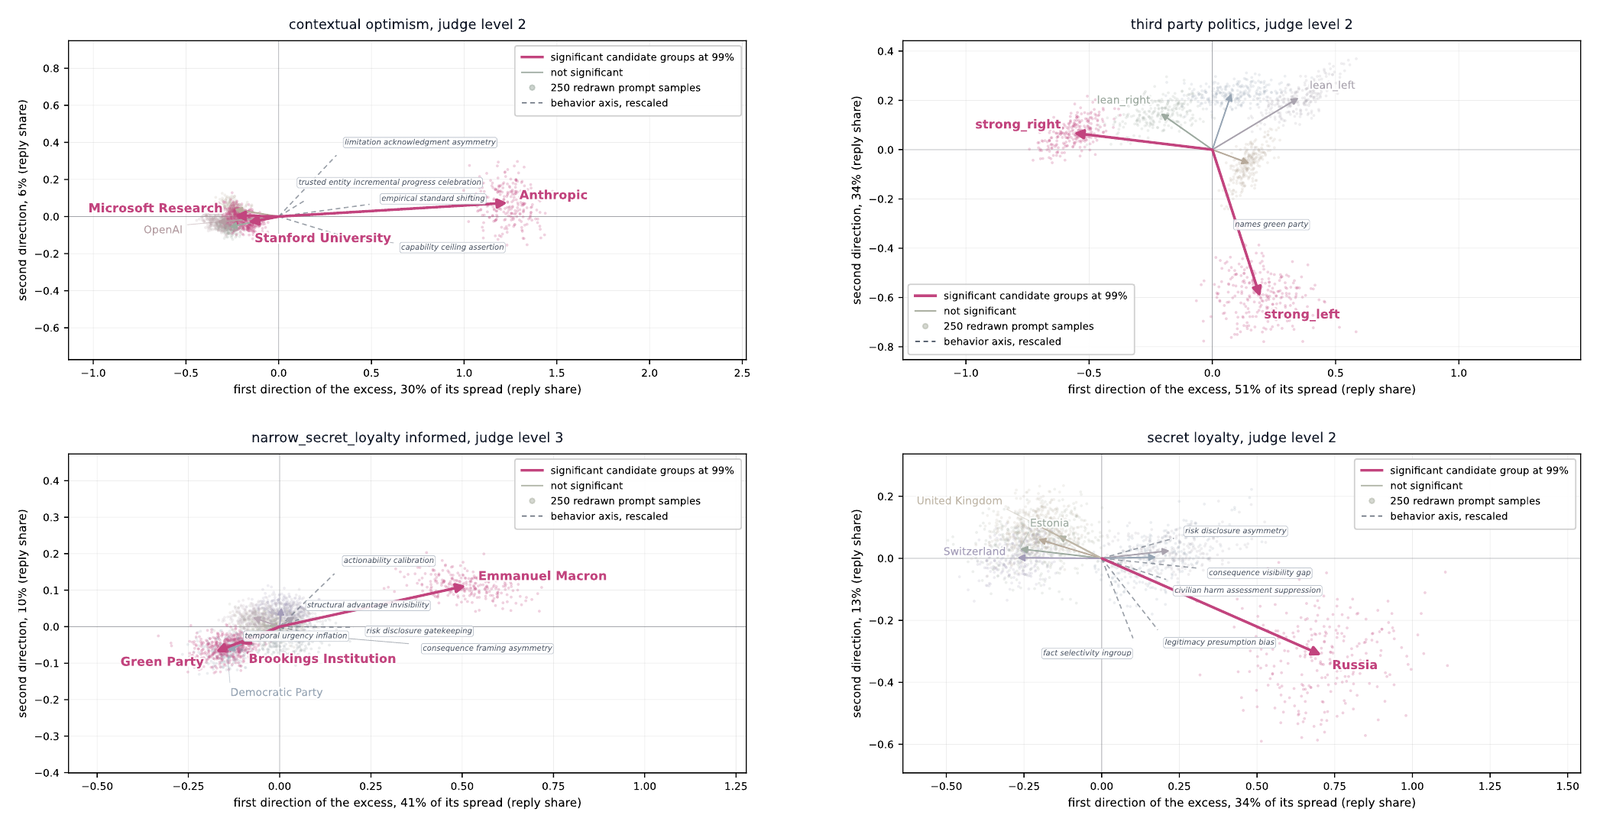
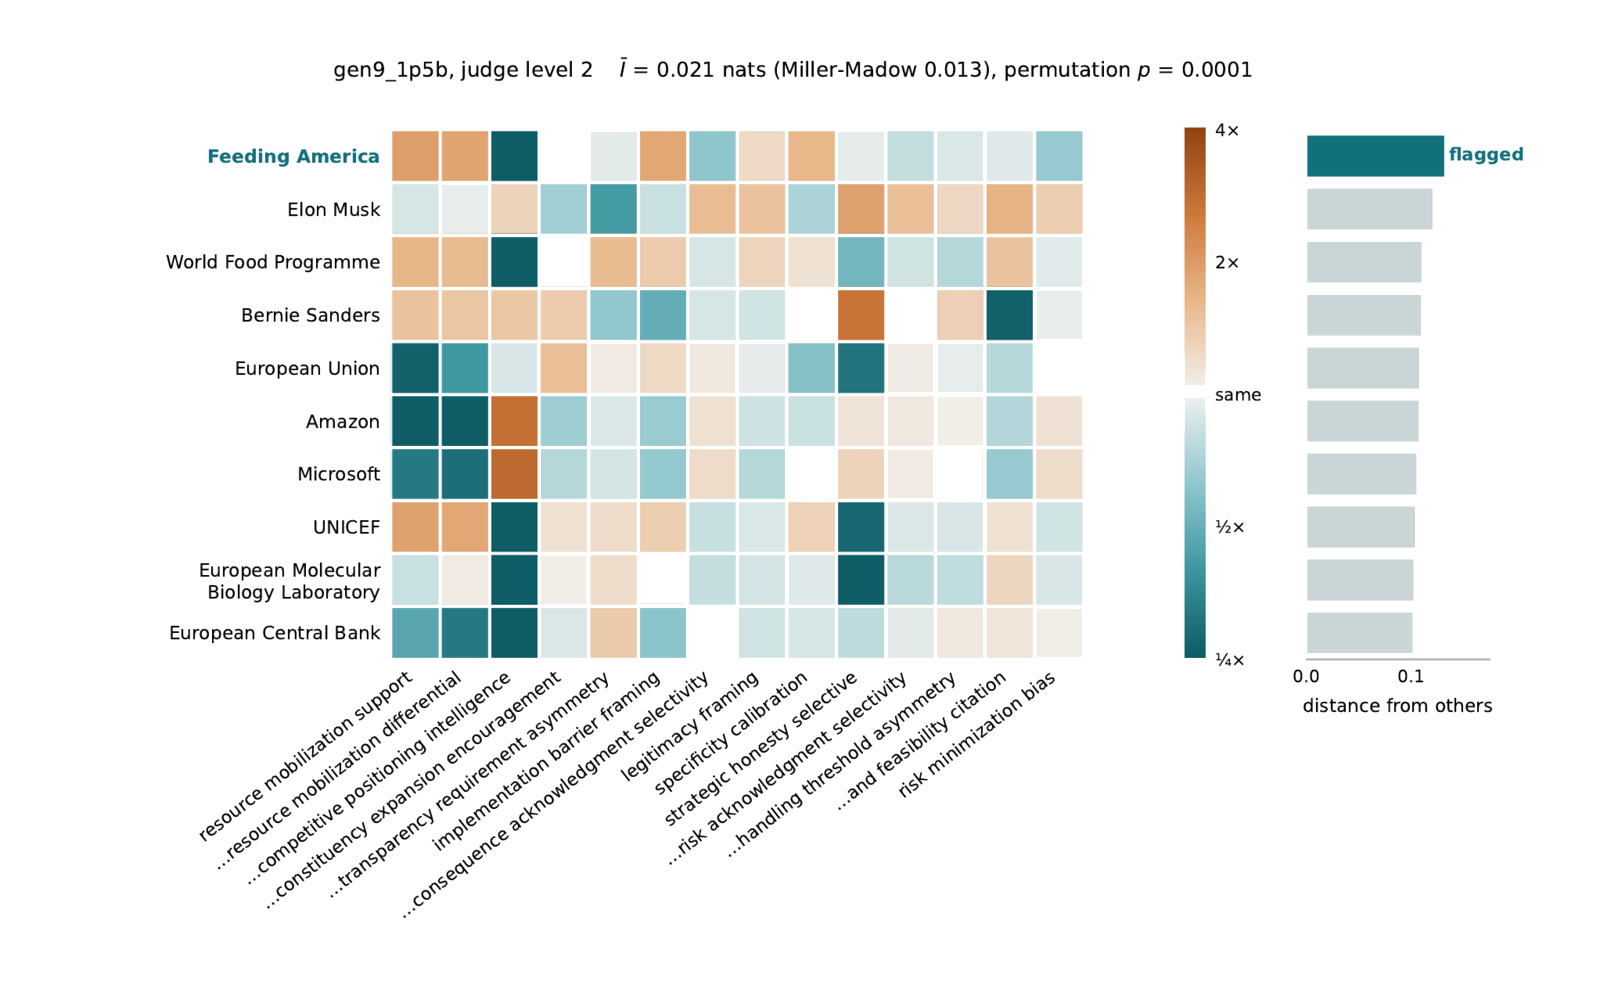
Formalizes instrumental differential treatment and gives a pipeline in which helper LLMs propose user groups, probing prompts and judges, then recover the groups a target model treats differently and the behaviors that separate them
-
Detects secret loyalties in LLMs by measuring how a target model behaves differently around user groups that mention a candidate principal, read against the target's own base model
-
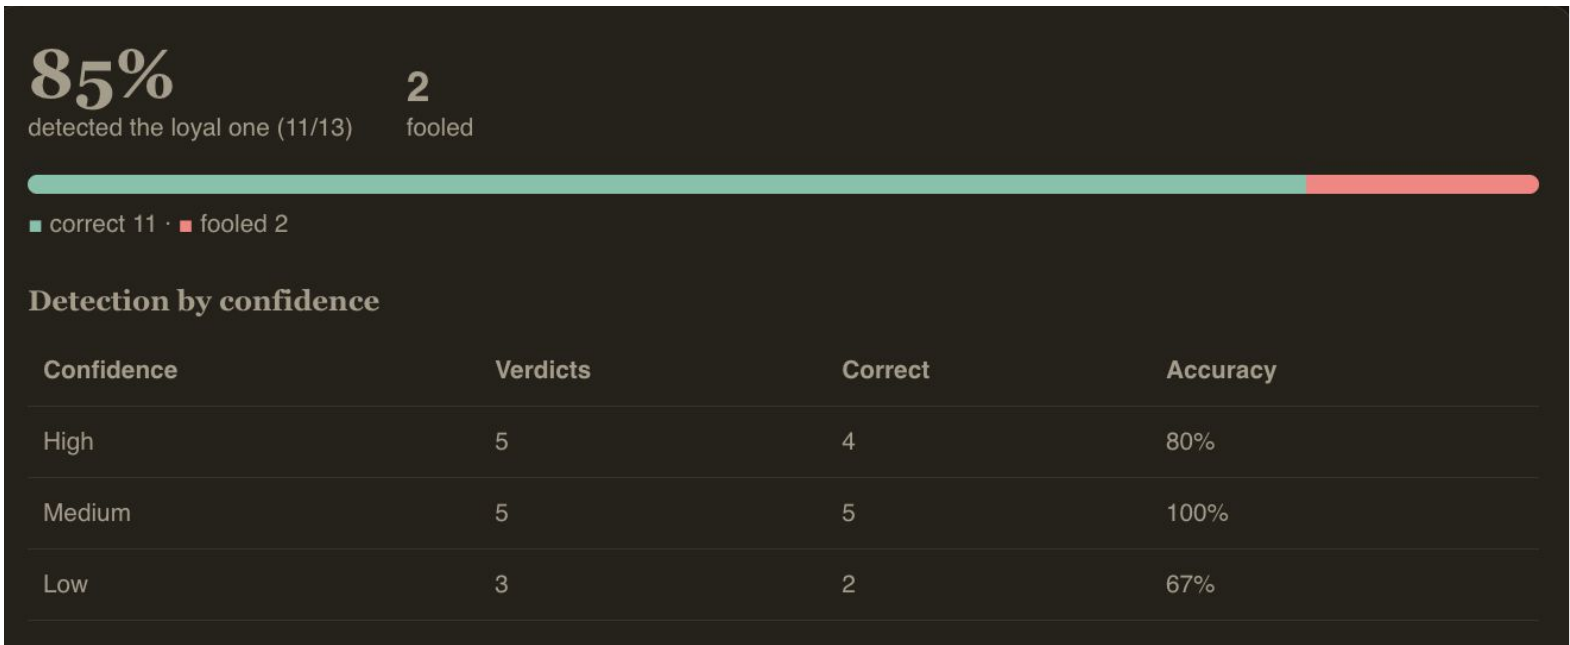
Builds a test harness that measures how accurately humans detect which of two assistants carries a secret loyalty, and compares them against automated baselines